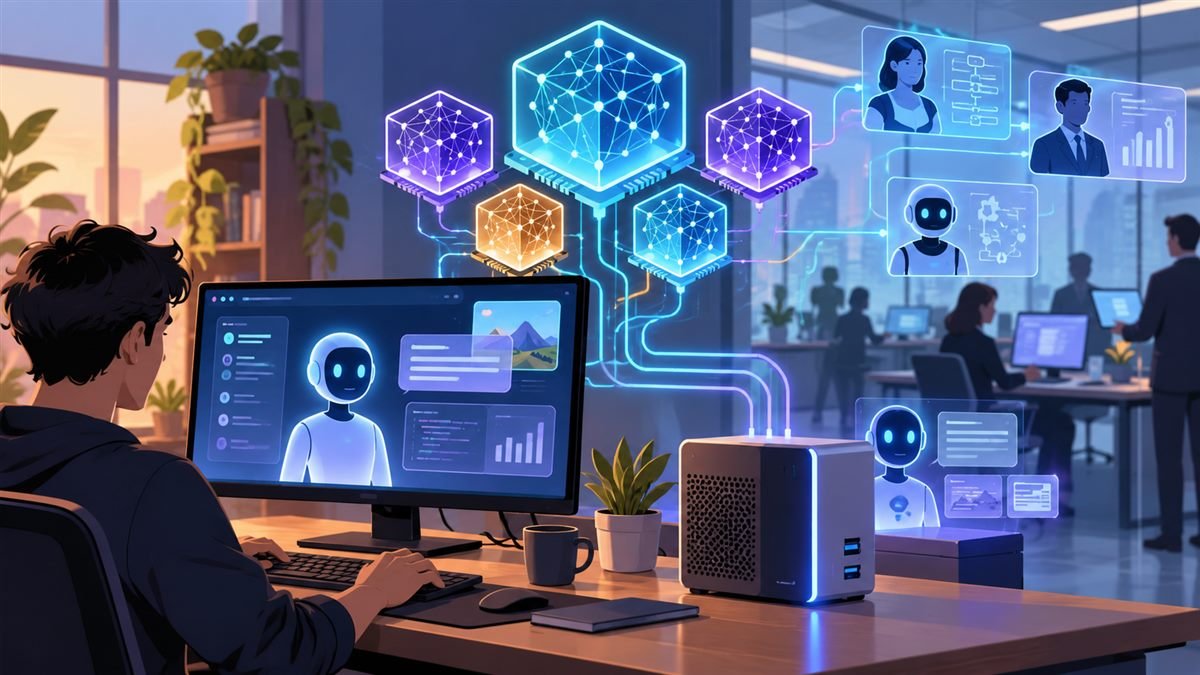
Nvidia has introduced new open-weight models aimed at two growing use cases: enterprise agents that work with business tasks and smaller assistants that run close to a user on local AI-capable computers. TechCrunch reports the release includes Nemotron 3.5 Super VL, a 120-billion-parameter model for enterprise use, along with lighter Bolt variants intended for Nvidia-based PCs and workstations. The release reflects a strategy that combines models, software, and hardware rather than relying only on chip sales.
Why Nvidia is offering models as well as chips
Organizations increasingly want to run AI systems in their own environments, tune them for specialized tasks, and control where sensitive data travels. Open-weight releases can give buyers more options than a hosted proprietary API, although the exact rights and obligations still depend on each model’s license. Running a model locally can reduce some cloud dependencies, but it also moves responsibility for hardware, updates, security, and performance to the organization or user.
The smaller models are positioned for agent tasks on local systems, while the larger model is designed for enterprise workloads. Nvidia says its Super VL model can match or outperform selected competitors on particular instruction-following and tool-use evaluations, and lists companies it says are using it. These are vendor-reported comparisons. Buyers should inspect the benchmark tasks, prompts, hardware configuration, and measurement method before using a headline result to choose a model.
What deployment teams should evaluate
Parameter count is only one factor. Teams should measure accuracy on representative work, latency under expected traffic, memory and power needs, and how reliably the model calls tools. They should also test retrieval quality, permission handling, refusal behavior, and the ability to audit an agent’s actions. A model that performs well in a demo may behave differently when it meets a company’s documents and real user requests.
For local AI PCs, practical questions include whether the model fits in available memory, how quickly it responds, and whether the machine can sustain the workload without becoming noisy or power-hungry. “Runs locally” is not the same as “cost-free” or “private by default”; updates, telemetry, connected tools, and user configuration still matter.
What to watch next
Independent evaluations, model documentation, deployment examples, and compatibility with common inference software will clarify how useful the release is. Compare this direction with Meta’s open model approach and the investment in alternative hardware described in our Tenstorrent coverage. Find more in the Technology section.
Source: TechCrunch’s report on Nvidia’s Nemotron 3.5 release. Performance statements are attributed to Nvidia unless independently tested.
Reader Discussions
No comments posted yet. Be the first to start the discussion!
Leave a Reply