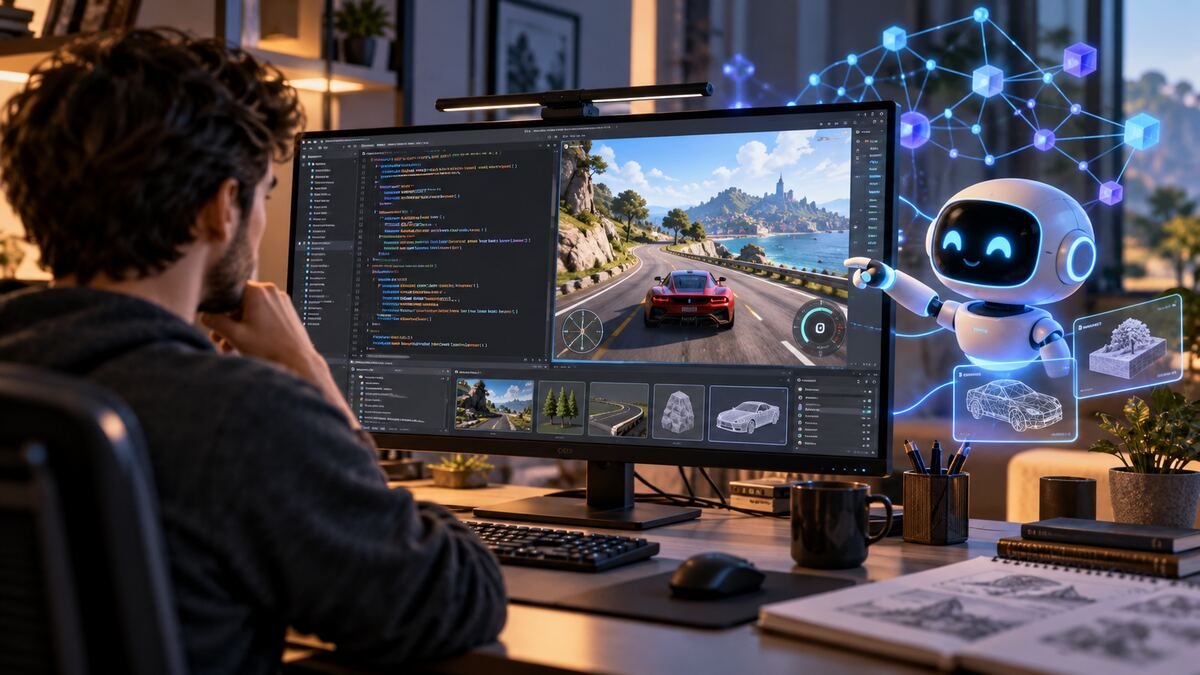
DeepSeek has released a new version of its V4.1 Flash model, named V4.1-Flash-1017, and says the update is aimed at building complete projects rather than only answering isolated coding questions. The announcement also opens Search and Fetch API endpoints to users and publishes model weights. For developers choosing a coding assistant, the release is a prompt to evaluate the full workflow: quality, latency, integration effort, and the cost of a completed task.
What DeepSeek says is new
In its October 17 release notes, DeepSeek describes stronger benchmark performance, faster task completion and shorter outputs compared with the previous version. The company says it used reinforcement learning with self-feedback to improve end-to-end project development, including examples such as a browser game and 3D modeling. These are vendor claims and demonstrations; teams should test their own tasks before assuming the same performance in production.
The update is available through DeepSeek’s website, app and API. DeepSeek also lists compatibility work with its own Harness and third-party development environments. The official documentation says Search and Fetch API calls cost $0.75 per 1,000 calls, with calls through certain server-side tools currently free for DeepSeek API users until billing begins on October 31, 2026. Pricing and eligibility can change, so check the documentation before shipping an integration.
Why project-level coding matters
A coding model that can turn a broad request into a working project has to handle more than syntax. It needs to break work into steps, create and connect files, run checks, respond to errors and preserve a coherent result. Better long-horizon performance could reduce the number of manual handoffs for prototypes, but a convincing demo is not the same as a production-ready application.
For software teams, the important question is whether the model can complete tasks inside the team’s existing environment. A useful evaluation set should include a small feature, a bug fix, a codebase question and a task that requires reading project context. Record whether the result passes tests, how often a person has to intervene, and how much time the review takes. Track total cost per successful task rather than comparing headline token prices alone.
How to evaluate it safely
- Start in a disposable branch or sandbox with no production credentials.
- Use representative tasks that have clear acceptance criteria and tests.
- Review generated code for security, licensing and dependency changes.
- Measure latency, retries, tool calls and human review time alongside pass rate.
- Compare the model with the system your developers already use, not just with a public benchmark.
Open model weights can give organizations more options for deployment and experimentation, but “open source” does not automatically mean easy or cheap to run. Check the license, hardware requirements, serving stack and update process. If a hosted API is the practical choice, verify data handling and retention terms before sending private source code.
What to watch next
The release highlights two directions in AI development: models are being optimized for completing workflows, and model vendors are extending their APIs with search and retrieval tools. Those tools can make assistants more useful, while also creating new requirements for permissions and source checking. Our earlier articles cover how autonomous agents are changing enterprise workflows and why agent access boundaries matter.
Source: DeepSeek API documentation, October 17, 2026. Performance descriptions above are attributed to DeepSeek; independent testing is needed for specific workloads.
Reader Discussions
No comments posted yet. Be the first to start the discussion!
Leave a Reply